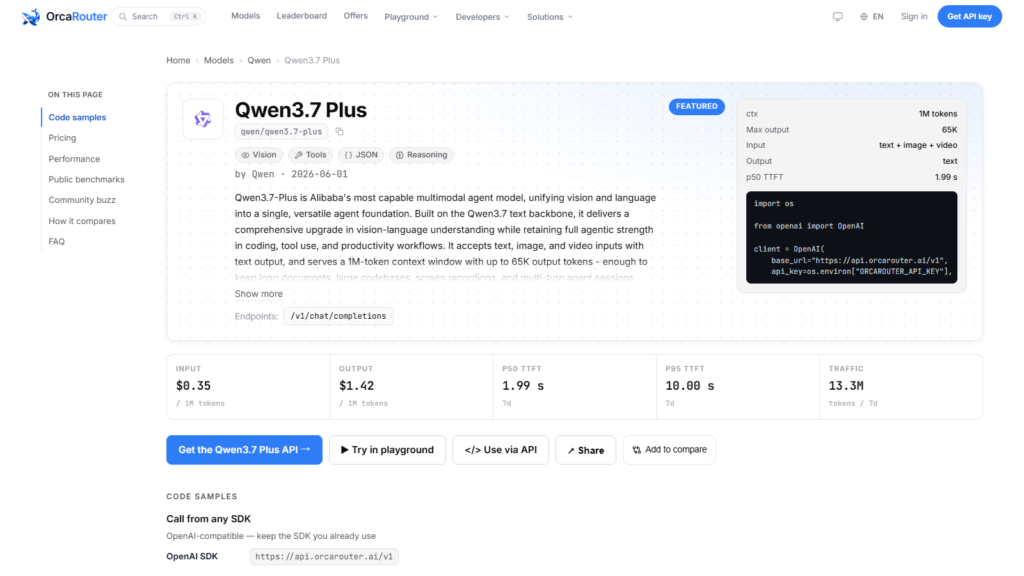
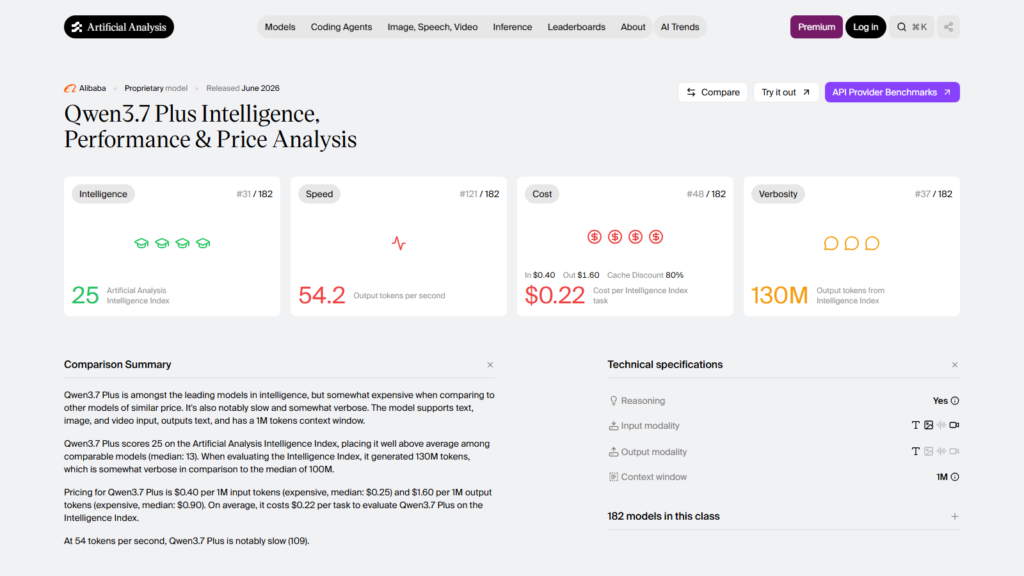
On OrcaRouter we host the Qwen3.7 Plus model — the mid rung of Qwen’s previous-generation family, shipped on June 1, 2026, priced at $0.35 per million input tokens and $1.42 per million output, with a 1M-token context window and a 64K maximum output. Artificial Analysis scores it 25 — the lowest Intelligence Index reading of any Qwen model that has one — with an output speed of 54.2 tokens per second and a per-task cost of $0.22. In production its p50 time-to-first-token is 2.98 seconds. It is carried at list price on the same key as every other Qwen model, with the live telemetry on the linked page.
A card that occupies the middle of its family’s price ladder while ranking last on the independent board is a card that demands a decision — and this article is about making that decision honestly.
Last on the board, mid on the ladder
The independent record is unambiguous: 25 on the Intelligence Index is the lowest score among the Qwen cards on the board, against the Max rung’s 45 and the Plus rung’s own mid-positioning. The score is not a misprint and not a rounding — it is the benchmark site’s reading of a previous-generation mid card, and this article will not soften it. What the score does not say is what the card is for; it says what the card is not: it is not a ceiling card, and buying it as one is the one way to be disappointed.
The honest framing is the price ladder instead. At $0.35 / $1.42 with a 1M window and a 2.98-second first token, Qwen3.7 Plus sits between the value rungs and the premium rungs — cheaper than the Max cards, stronger-priced than the Flash cards — and that middle seat, not the index row, is where its argument lives.
The family’s middle seat
| model | context | input / output | AA index | output speed | per-task cost | p50 TTFT |
| Qwen3.7 Max | 1M | $1.25 / $3.75 | 29 | 199.8 tok/s | $1.15 | 1.27 s |
| Qwen3.7 Plus | 1M | $0.35 / $1.42 | 25 | 54.2 tok/s | $0.22 | 2.98 s |
| Qwen3.7 Flash | 1M | $0.03 / $0.13 | no page on AA | — | — | 3.83 s |
Context windows and rate cards are what Qwen lists; the index scores, output speeds and per-task costs are Artificial Analysis’ live readings; the TTFT column is production telemetry from the linked pages. The table is the upgrade map of the previous generation: four points of index between the Max and the Plus, and a price gap of over three times — the vendor’s way of saying the Max rung costs more for a modest score gain. The Plus card’s per-task cost of $0.22 is the column worth noticing: it is a fifth of the Max rung’s, which is the whole case for the middle seat.
The honest trade at 54.2 tokens a second
The 54.2 tokens per second output speed is the quietest number on the card and worth the longest look. It is roughly a quarter of the Max rung’s 199.8, which means the same long generation takes four times as long on the Plus — a real cost for report-length output, and the figure that pushes interactive, generation-heavy work up the ladder. The per-task cost of $0.22 is the compensating arithmetic: at a fifth of the Max rung’s cost, the Plus rung is priced for the workloads that accept slower output in exchange for a cheaper standard task.
The production record adds the market’s answer: 20.1 million tokens a week. That is real usage but the smallest of the family’s rungs — the market is not flowing volume to this seat the way it does to the Flash cards, and not paying premium traffic the way it does to the Max. The reading is honest: the middle seat is being sampled, not adopted at scale, and this article’s numbers are exactly why — a 25 score, a slow output, and a price that is only compelling when neither of those matters.
The 20.1 million figure deserves one comparison before it becomes a dismissal. The rungs around it tell the same story the index does: the cheap Flash card below moves 746.3 million tokens and the premium Max above moves 64.4 million, which puts the middle seat in the unusual position of being beaten from both sides of the price ladder. The buyers who want volume go down to three cents and the buyers who want ceiling go up to $1.25 input; the seat in the middle holds the thin slice of workloads that need more than the floor but less than the ceiling. It is not a verdict on the card — it is a map of where the middle of a price ladder sits in a market that has learned to split sharply.
When the middle seat is the right seat
There is a profile that fits this card precisely, and it is the profile of the workload, not the model: input-heavy, context-deep, output-modest, quality bar set to competent. Large-corpus analysis over a 1M window, extraction and classification at volume, first-pass drafting that a stronger card will polish — each leans on the cheap $0.22 per-task arithmetic and the full megabyte of context, and none is punished by 54.2 tokens per second or a 25 score. For that profile, the middle seat is not the worst of both worlds; it is the seat priced for the job.
The discipline is to check the workload before trusting the seat. The moment a task needs a higher reasoning ceiling, or generation-heavy output, or the fastest first token — the moment any of the card’s three weak numbers becomes the requirement — the middle seat is the wrong buy, and the ladder above it has the rung that fits. Buy the card for what it is, not for where it sits, and the 20.1 million weekly tokens on the linked page will keep their honest meaning.
The takeaway
Qwen3.7 Plus is the mid rung of Qwen’s previous generation: $0.35 / $1.42, a 1M context window, a 64K maximum output, and a 2.98-second p50 first token on our production record. Artificial Analysis scores it 25 — the lowest index reading of any Qwen model that has one — at 54.2 tokens per second and $0.22 per task. Its 20.1 million weekly tokens show a card being sampled, not adopted at scale, and this article has laid out why: a slow output and a mid score, priced for the workloads that can live with both. If the workload is input-heavy and output-modest, the middle seat fits — live at list price, with the telemetry on the linked page.
Sourcing note: release date, context window and rate card are what Qwen lists and have not been independently reproduced. The Intelligence Index score, output speed and per-task cost are from Artificial Analysis’ live model page, read 2026-10-08. The p50 time-to-first-token and seven-day token volume are OrcaRouter production telemetry from the linked model page. All checked 2026-10-08.
